OpenWAM:可组合世界-动作模型开放框架
OpenWAM: An Open Framework for Composable World-Action Models
OpenWAM 提出面向机器人的可组合世界-动作模型开放框架,基于适配的 Wan2.2-5B 构建 5B 视频专家与 2B 动作专家的 Mixture-of-Transformers 架构。
A framework for world–action models
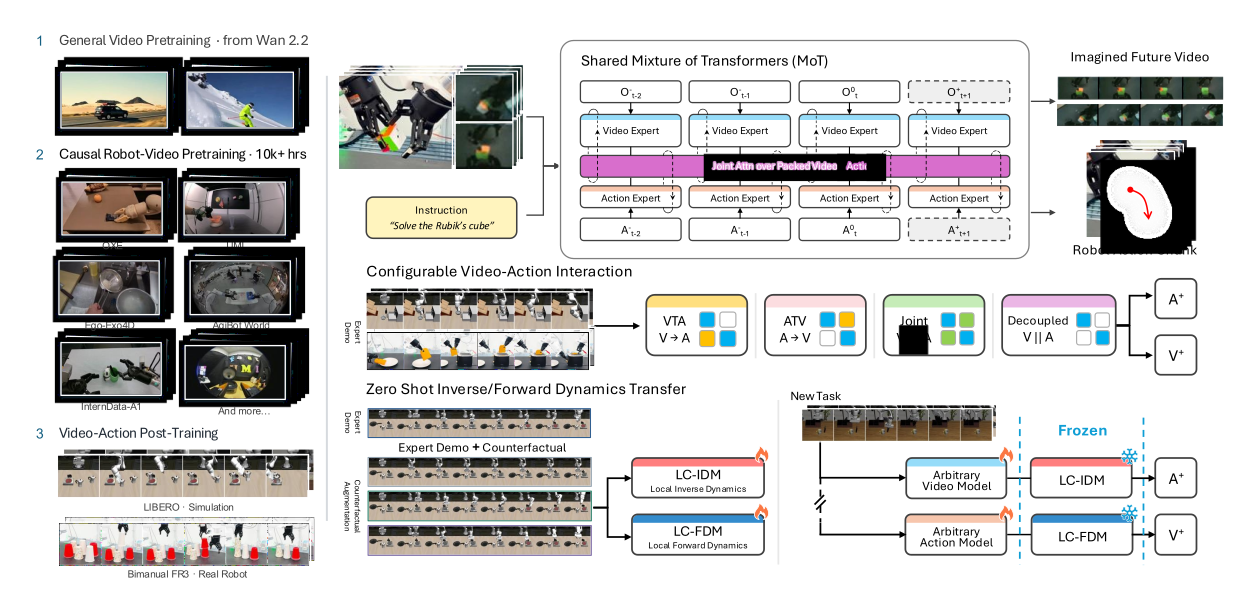
Should a robot predict what it will see before deciding how to act, or generate both together? World–action models make both possible. Comparing these choices is difficult when every system uses a different backbone, dataset, and training recipe. OpenWAM gives them a common foundation so we can study how prediction and control work together.
The framework supports composition within a model and between models. We can change the order in which video and actions are generated and how their tokens attend to one another. We can also connect independently trained components: a video predictor proposes a future, an inverse dynamics model turns it into actions, and a forward dynamics model predicts what a supplied action sequence will do.
A shared video–action architecture
Before learning actions, we adapt Wan2.2-5B to robot motion and interaction. We pretrain on approximately 3.34 million trajectories and recordings—14.64k hours of source video—spanning real and synthetic robot manipulation, human-guided manipulation, and human interaction. This stage uses video alone, without action labels or proprioceptive inputs.
What goes into pretraining?
| Dataset | Trajectories / takes | Hours |
|---|---|---|
| Open X-Embodiment | 1,300,749 | 1,911.29 |
| AgiBot World Beta | 1,003,672 | 2,976.4 |
| Ego-Exo4D v2 | 5,035 | 221.26 |
| InternData-A1 | 637,498 | 7,433.91 |
| RoboCOIN | 183,157 | 1,306.83 |
| RoboMIND | 107,877 | 305.5 |
| FastUMI-100K | 92,823 | 461.77 |
| UMI family | 5,430 | 24.60 |
Paper Table 8 · Hours count source sequences before training-window sampling, including synthetic and human-interaction video. OXE covers 49 manipulation datasets; InternData-A1 is synthetic; Ego-Exo4D records human interaction. The UMI family includes UMI, DexUMI, UMI on Legs, and MV-UMI.
Causal attention lets us generate video a chunk at a time: each chunk can use current and past observations and earlier chunks, but not later ones. Its tokens are denoised together. After 14 days on 32 NVIDIA B200 GPUs, this checkpoint provides the visual foundation for the downstream models.
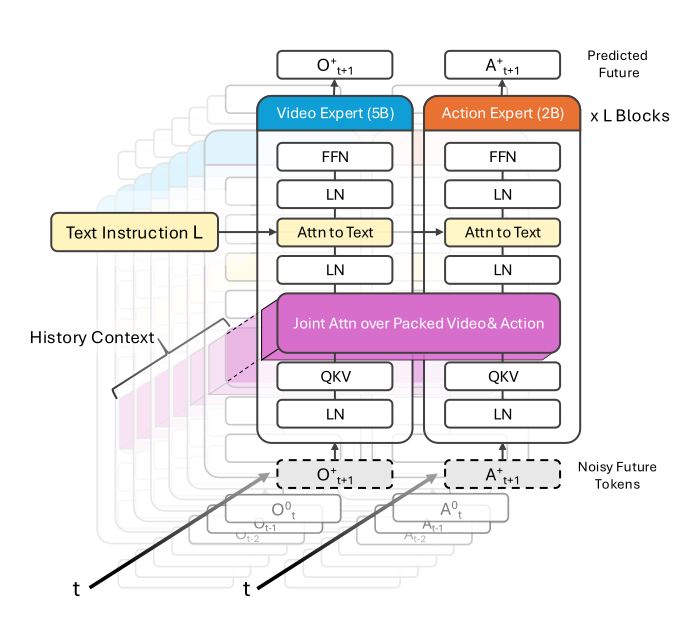
To add robot control, we pair the 5B video expert with a 2B action expert in a Mixture-of-Transformers (MoT) architecture. The action expert starts from width-adapted copies of the pretrained video layers. Each expert keeps its own normalization, projections, and feed-forward layers; attention over their combined tokens lets them exchange information.
Video-action interaction programs
The same architecture can predict video before actions, actions before video, or both at once. Each interaction program specifies the generation order and attention between future tokens. The backbone, tokenization, training objective, and downstream recipe stay fixed, and every program receives the task instruction and observed history.
| Program | Generation and conditioning |
|---|---|
| Video-then-action (VTA) | Predict video first, then generate actions conditioned on that video. |
| Action-then-video (ATV) | Generate actions first, then predict video conditioned on those actions. |
| Joint | Denoise video and actions together, with attention in both directions. |
| Decoupled | Predict video and actions without attention between their future tokens. |
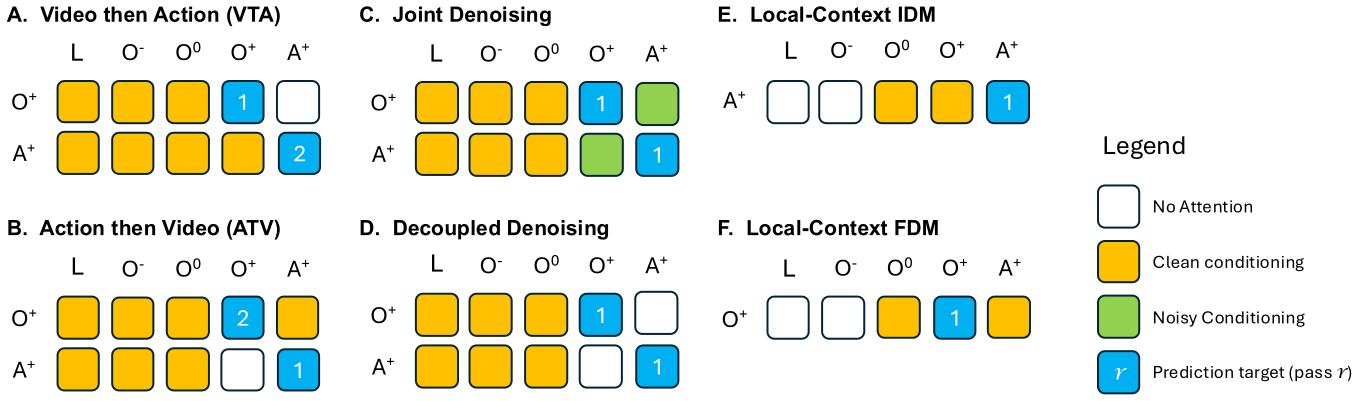
All programs use latent flow matching, with four latent video frames aligned to each 16-step action chunk and proprioception supplied per chunk. In VTA and ATV, the second stage learns from recorded trajectories during training and uses the first stage’s predictions at inference.
Beyond policies: local-context IDM and FDM
A task-conditioned predictor proposes what should happen next. Dynamics models connect that proposal to the robot’s motion: inverse dynamics (IDM) turns a visual future into actions, while forward dynamics (FDM) predicts the outcome of an action sequence. OpenWAM supports both as standalone models.
We give them a local-context interface: the current observation, proprioception, and a supplied future trajectory.
Local-context IDM: current observation + proprioception + supplied future video → action trajectory.
Local-context FDM: current observation + proprioception + supplied action trajectory → future video.
Neither model receives task language or pre-start history. This separates choosing a task from modeling a transition: we can adapt the video predictor and ask whether the same IDM still produces the right actions. The experiments below test how far this local information can take us.
The video predictor passes VAE video latents to the IDM, not transformer hidden states or caches. With compatible video and action representations, the components can be trained separately and connected at inference. An FDM can likewise predict the outcome of actions from a separate policy.
Learning from alternative outcomes
A demonstration shows what the demonstrator chose to do, but says little about what other actions would have caused. Changing a model’s inputs does not fill that gap in its training data. We build LIBERO-Long-CF: 32,000 counterfactual segments across ten tasks by restoring simulator states and trying alternative action sequences, including unsuccessful ones. The models learn from the resulting observations and actions, without access to simulator state.
| Quantity | Demonstrations | LIBERO-Long-CF |
|---|---|---|
| Tasks | 10 | 10 |
| Stored sequences | 500 | 32,000 |
| Sequences per task | 50 | 3,200 |
| Controls per sequence | 276.2 mean | 128 |
| Total controls | 138,090 | 4,096,000 |
| Control-equivalent hours | 1.92 | 56.9 |
Paper Table 9 · Equivalent durations at 20 Hz. Each counterfactual segment contains 128 controls and 129 synchronized two-view observations. The dataset contains 29.7× as many control records as the demonstrations, using the original tasks, assets, and physics.
What changes in the counterfactual rollouts?
We vary motion magnitude, direction, timing, individual action axes, and gripper behavior. 75% of segments start along a demonstration; the other 25% start after an additional action perturbation.
| Intervention family | Fraction (%) |
|---|---|
| Stop / rescale arm motion | 9.4 |
| Reverse / redirect translation | 6.3 |
| Axis biases and pulses | 12.5 |
| Dedicated yaw perturbation | 3.1 |
| Noise / randomized arm controls | 12.5 |
| Dedicated gripper interventions | 31.3 |
| Random-duration arm / gripper interventions | 25.0 |
Intervention recipes (%) · Paper Table 10. Values are rounded; different recipes can produce overlapping physical effects.
In the perturbed starts we analyzed, the end effector is on average 3.34 cm from the nearest point on the demonstrated path (median 1.90 cm). Objects also move beyond their demonstrated configurations in 61.6% of these starts, measured at thresholds of 1 cm translation, 5° rotation, or 5% articulated-joint travel.
| Measured interaction | Rate (%) |
|---|---|
| Gripper–object / fixture contact | 90.4 |
| Detected grasp | 50.0 |
| Object-configuration effect | 72.3 |
Interaction rates (%) · Paper Table 11. Measured over the segments analyzed; a segment can count toward multiple categories. Object changes are measured against the reference rollout from the same starting state.
Branches from the same starting state stay together in the train/test split. Each transition supplies its own training example; the loss does not directly contrast pairs of branches.
We compare models trained on demonstrations alone, counterfactuals alone (CF-only), and a mixture of 60% counterfactuals and 40% demonstrations.
Policy performance across programs
LIBERO
VTA achieves 98.6% mean success across four LIBERO suites. Each evaluated program exceeds 95% on LIBERO-Long.
| Method | Object | Goal | Spatial | Long | Mean |
|---|---|---|---|---|---|
| OpenVLA | 88.4 | 79.2 | 84.7 | 53.7 | 76.5 |
| OpenVLA-OFT | 98.4 | 97.9 | 97.6 | 94.5 | 97.1 |
| π0 | 98.8 | 95.8 | 96.8 | 85.2 | 94.1 |
| π0.5 | 98.2 | 98.0 | 98.8 | 92.4 | 96.9 |
| GR00T-N1 | 97.6 | 93.0 | 94.4 | 90.6 | 93.9 |
| Motus | 99.8 | 96.6 | 96.8 | 97.6 | 97.7 |
| Fast-WAM | 100.0 | 97.0 | 98.2 | 95.2 | 97.6 |
| LingBot-VA | 99.6 | 97.2 | 98.5 | 98.5 | 98.5 |
| OpenWAM-VTA | 99.4 ± 0.3 | 98.4 ± 0.5 | 98.6 ± 0.2 | 97.8 ± 0.4 | 98.6 |
| OpenWAM-ATV | 98.0 ± 0.4 | 97.2 ± 0.2 | 96.6 ± 0.6 | 95.4 ± 0.3 | 96.8 |
| OpenWAM-Joint | 98.2 ± 0.2 | 97.8 ± 0.4 | 97.6 ± 0.3 | 96.6 ± 0.5 | 97.6 |
| OpenWAM-Decoupled | 99.0 ± 0.3 | 98.0 ± 0.2 | 97.8 ± 0.5 | 97.0 ± 0.4 | 98.0 |
Closed-loop success (%) · Paper Table 3. OpenWAM: mean ± standard deviation over three training seeds, with 50 episodes per task and 500 per suite per seed. Baselines are reported as published in their respective papers.
Decoupled remains competitive with Joint on LIBERO-Long: 97.0% versus 96.6%. Strong control on this benchmark does not require attention between future video and action tokens.
Bimanual manipulation
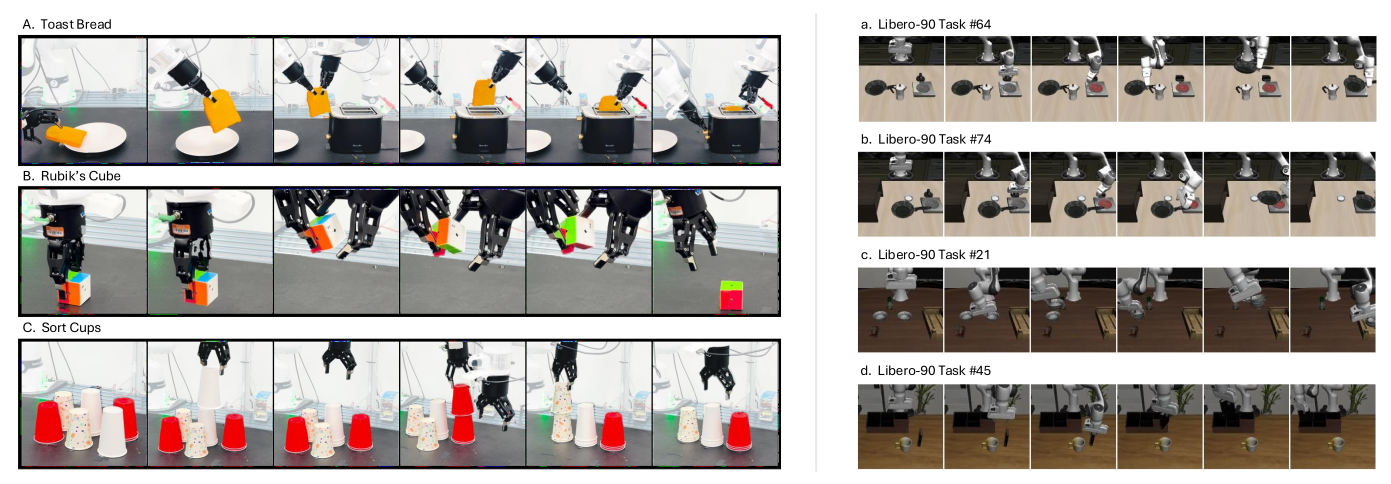
On a bimanual robot, VTA and Joint each average about 92% success across toasting bread, completing the final layer of a 2 × 2 Rubik’s cube, and sorting cups by color. The setup uses two Franka Research 3 arms with parallel-jaw grippers, two wrist cameras, and a third-person camera.
| Method | Toast | Cube | Cups | Mean |
|---|---|---|---|---|
| OpenWAM-VTA | 92.0 | 90.0 | 94.4 | 92.1 |
| OpenWAM-Joint | 90.0 | 94.0 | 91.7 | 91.9 |
Closed-loop success (%) · Paper Table 4. We train on 200 toast, 200 cube, and 180 cup demonstrations, each about 30 seconds, and evaluate on 50, 50, and 36 trials per method, respectively.
What do pretraining and MoT contribute?
Starting from a general-purpose video model helps, but adapting it to robot video makes a substantial difference. Our causal robot-video pretraining improves LIBERO-Long success over the original Wan2.2 initialization by 29.4 points for VTA and 34.4 points for Joint.
| Video initialization | VTA (%) | Joint (%) |
|---|---|---|
| Random initialization | 20.0 | 27.2 |
| Original Wan2.2 | 68.4 | 62.2 |
| Robot-video pretrained | 97.8 | 96.6 |
LIBERO-Long success (%) · Paper Table 12. Architecture and downstream training are fixed within each program; robot-video data and causal attention are introduced together.
The architecture also matters. Giving video and actions separate experts improves VTA by 5.0 points and Joint by 3.0 points over a shared DiT that processes both modalities.
| Architecture | VTA (%) | Joint (%) |
|---|---|---|
| Shared DiT (non-MoT) | 92.8 | 93.6 |
| MoT | 97.8 | 96.6 |
LIBERO-Long success (%) · Paper Table 13. Both architectures use the same robot-video-pretrained backbone, downstream data, and training settings.
What makes a frozen IDM transfer?
Can we teach the video predictor a new task without retraining its action component? We freeze IDMs trained on LIBERO-Long and pair them with video predictors adapted to four LIBERO-90 tasks. Each predictor comes from a VTA model trained on target-task demonstrations, including their action labels; only the IDM is reused without further training.
With the same mixture of demonstrations and counterfactuals, the local-context IDM reaches 84.0% mean success, compared with 47.0% for the full-context IDM.
| Action component / reference | Task 64 Composition | Task 74 Retarget | Task 21 Object / grasp | Task 45 Scene shift | Mean |
|---|---|---|---|---|---|
| Task-tuned VTA reference | 94 | 86 | 92 | 100 | 93.0 |
| Full-context IDM · demo-only | 88 | 90 | 0 | 0 | 44.5 |
| Full-context IDM · mixed | 54 | 92 | 4 | 38 | 47.0 |
| Local-context IDM · demo-only | 36 | 50 | 0 | 0 | 21.5 |
| Local-context IDM · CF-only | 80 | 92 | 90 | 76 | 84.5 |
| Local-context IDM · mixed | 74 | 86 | 88 | 88 | 84.0 |
| Original VTA · unadapted reference | 42 | 0 | 0 | 0 | 10.5 |
Success (%) · Paper Table 5. The four target tasks are outside the IDM’s LIBERO-Long training set. Within each task, IDM variants share the adapted video predictor and rollout protocol. VTA references run as complete policies.
The targets are stacking bowls in a tray (64), putting a book in a caddy’s left compartment (74), turning on a stove and placing a pan on it (21), and repeating the stove task in a different scene (45).
Counterfactual data is crucial here. The same local-context IDM trained only on demonstrations averages 21.5%; adding counterfactual transitions raises it to 84.0%, and CF-only training reaches 84.5%. A local interface becomes much more useful when the model has seen a wider range of action outcomes.
Keeping demonstrations in the mix also helps the composed model retain its original skills: source-task success is 94.4%, versus 90.6% with CF-only training, while their transfer means remain close.
| Action component | Supervision | LIBERO-Long |
|---|---|---|
| Full-context IDM | Demo-only (native VTA) | 97.8 |
| Full-context IDM | Mixed | 92.2 |
| Local-context IDM | Demo-only | 25.8 |
| Local-context IDM | CF-only | 90.6 |
| Local-context IDM | Mixed | 94.4 |
Source-task success (%) · Paper Table 6. All action models use the LIBERO-Long video predictor.
Do predicted futures follow the actions?
For forward dynamics, the question is whether changing the actions changes the predicted future correctly. We test 2,560 counterfactual futures: 16 action branches from each of 160 starting contexts across ten LIBERO tasks. Every model receives the same initial observations and candidate actions.
| Supervision | RGB MSE ↓ | Outcome acc. K = 2 (%) ↑ | Outcome acc. K = 16 (%) ↑ |
|---|---|---|---|
| Demo-only | 14.35 | 68.3 | 21.1 |
| CF-only | 9.40 | 93.6 | 71.3 |
| Mixed | 9.62 | 91.8 | 67.7 |
Paper Table 7 · MSE in units of 10−3. Outcome accuracy asks whether the prediction’s closest match, by RGB MSE, is the supplied action’s actual outcome among K futures from the same starting state.
Counterfactual supervision improves both visual accuracy and the ability to distinguish action outcomes. CF-only training reduces RGB MSE by 34.5% and raises identification of the correct future among 16 alternatives from 21.1% to 71.3%.
Policy and dynamics in one model
So far, each dynamics model has been trained separately. We also train a single OpenWAM checkpoint on policy generation, inverse dynamics, and forward dynamics. It reaches 92.8% LIBERO-Long policy success versus 88.0% for UVA, a released system supporting the same three objectives, and outperforms UVA on the evaluated dynamics metrics.
A unified checkpoint is possible, but specialization still pays off. Dedicated policy models retain higher task success, while separately trained dynamics models give more accurate counterfactual video and end-effector position predictions.
| Model | FDM MSE ↓ | FDM SSIM ↑ | IDM pos. (cm) ↓ | IDM rot. (°) ↓ |
|---|---|---|---|---|
| Specialists · CF-only | 0.00940 | 0.8889 | 1.17 | 3.60 |
| Specialists · mixed | 0.00962 | 0.8859 | 1.22 | 3.68 |
| OpenWAM · multi-objective | 0.01416 | 0.8398 | 1.73 | 3.55 |
| UVA | 0.01514 | 0.8134 | 3.57 | 12.99 |
Counterfactual rollouts · Paper Table 14. Specialist rows pair independently trained IDM and FDM checkpoints. FDM compares agent-view images; IDM compares end-effector trajectories after executing actions from the same state. MSE is in raw units.
Demonstration results and training setup
Adding demonstrations to specialist training improves accuracy on demonstrated motions. The unified model gives the closest reconstructions here.
| Model | FDM MSE ↓ | FDM SSIM ↑ | IDM pos. (cm) ↓ | IDM rot. (°) ↓ |
|---|---|---|---|---|
| Specialists · CF-only | 0.00734 | 0.9126 | 1.76 | 2.39 |
| Specialists · mixed | 0.00186 | 0.9776 | 0.44 | 1.21 |
| OpenWAM · multi-objective | 0.00058 | 0.9934 | 0.43 | 1.10 |
| UVA | 0.00279 | 0.9645 | 2.03 | 1.60 |
Reconstruction on real demonstrations · Paper Table 14. Some demonstrations may also be used in policy training. Specialist rows pair separate IDM and FDM checkpoints. MSE is in raw units.
The unified model allocates 60% of training to joint video–action generation on demonstrations, 20% to local-context IDM, and 20% to local-context FDM. Within each dynamics objective, half the samples are demonstrations and half are counterfactuals.
Outlook and resources
A shared causal video backbone supports strong policies across interaction programs, while counterfactual data makes independently trained dynamics components more reusable. The next challenge is to extend this reuse from simulation to real robots, and forward prediction from local transitions to long-horizon planning.
Read the paper for the full method and experiments. The OpenWAM repository includes training, evaluation, and video-to-action composition code. Start with the quickstart or download the pretrained video-model weights.
Cite OpenWAM
@article{yu2026openwam,
  title   = {{OpenWAM}: An Open Framework for Composable World-Action Models},
  author  = {Yu, Heng and Yuan, David D. and Zhang, Juze and Chen, Changan and
             Feng, Yao and Baldonado, Michelle and Cousins, Steve and
             Fei-Fei, Li and Wu, Jiajun and Adeli, Ehsan},
  journal = {arXiv preprint arXiv:2610.07922},
  year    = {2026},
  url     = {https://arxiv.org/pdf/2610.07922}
}来源:Hacker News · openwam.stanford.edu